New to CatchCPT? Get 5 free credits to spend on any lesson — automatically added when you register. Plus earn rewards when you refer friends. Get started
Identifying Unique Cybersecurity Challenges Posed by Modern AI Models
1:56.7
The core problem in AI security is that powerful AI systems create new weaknesses that traditional cybersecurity tools do not fully address. A conventional security program may focus on firewalls, passwords, encryption, access control, malware detection, and software patching. These remain essential, but they do not solve the distinctive risks created by machine learning and generative AI. AI systems learn from data, which means attackers can target the data used to build them. They respond to inputs, which means attackers can craft inputs designed to mislead them. Large language models follow natural language instructions, which means malicious commands can be embedded in ordinary text. AI assistants may connect to tools, which means a misleading prompt can become a real action, such as sending a message, changing a file, querying a database, or initiating a transaction. Small manipulations can have outsized effects because models often rely on complex statistical patterns that are not obvious to humans. A document that appears harmless may contain instructions intended for the model rather than the person reading it. A software request that sounds routine may cause an AI coding tool to generate insecure code. A model that performs well in normal testing may fail under adversarial pressure. This matters because AI is moving from experimental use into everyday infrastructure. Organizations are using AI to process sensitive information, automate workflows, assist employees, and make decisions. If attackers can manipulate these systems, they can cause operational disruption, financial loss, privacy violations, legal exposure, and safety failures. The challenge is not merely that AI can be hacked.
AI Under Attack: Adversarial Inputs, Prompt Injection, and Model Security
Unlock to access all lessons, quizzes, and a certificate.
Related courses
 Corporate FinanceSeptember 2026
Hong Kong Takeovers, Mergers and Share Buy-backs
Legal & Compliance
 Artificial IntelligenceSeptember 2026
AI, Copyright, and the Ownership of Training Data
Legal & Compliance
 Artificial IntelligenceSeptember 2026
From Chatbots to Agents: The Phase of AI
Legal & Compliance
 Digital AssetsSeptember 2026
Virtual Assets and Tokenised Securities: Regulatory Issues for Financial Intermediaries
Legal & Compliance
More from this course
Understanding the Critical Need for Securing Artificial Intelligence Systems
AI Under Attack: Adversarial Inputs, Prompt Injection, and Model Security
2:00.3
Differences Between Traditional Software Security and AI Model Security
AI Under Attack: Adversarial Inputs, Prompt Injection, and Model Security
1:59.5
Foundational Principles for Securing AI Systems and Data Infrastructure
AI Under Attack: Adversarial Inputs, Prompt Injection, and Model Security
1:59.8
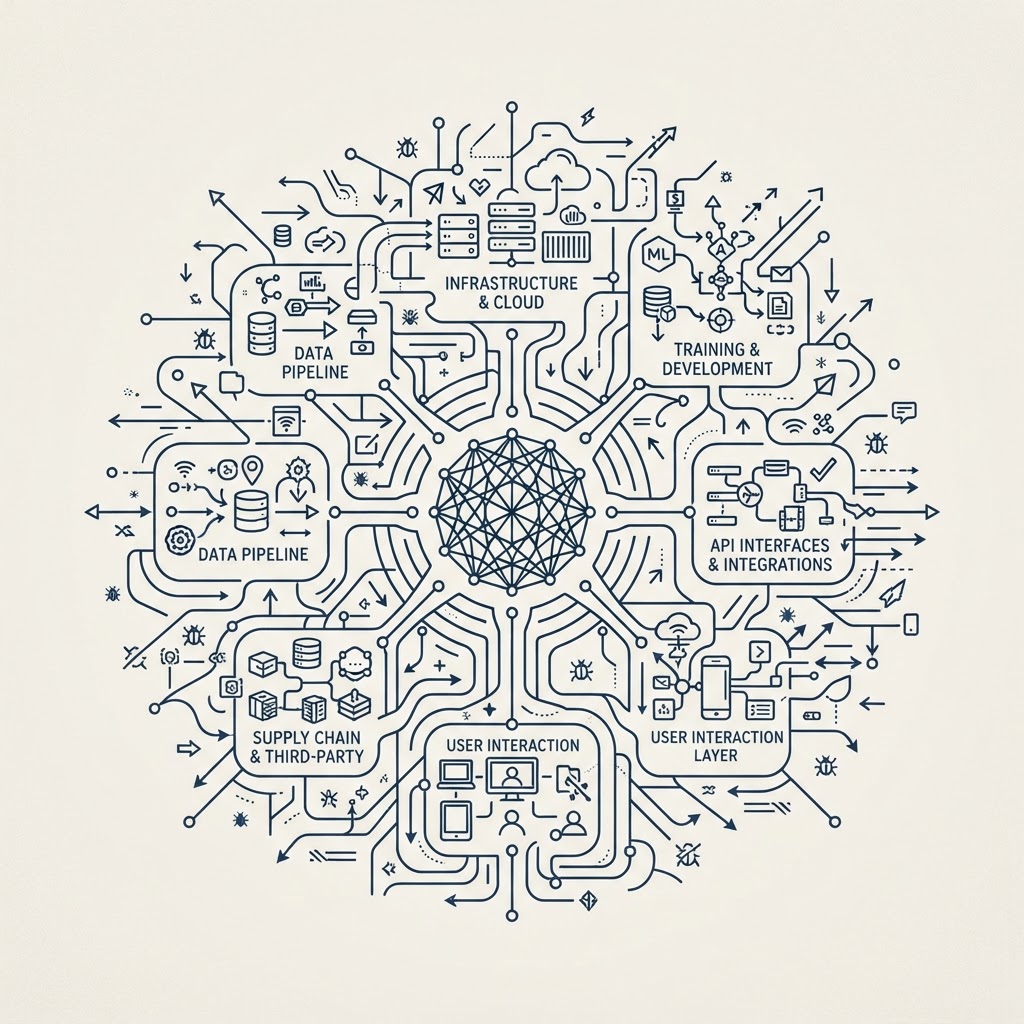
Mapping the Expanded Attack Surface of Modern AI Ecosystems
AI Under Attack: Adversarial Inputs, Prompt Injection, and Model Security
2:07.1
Related lessons
Hong Kong Takeovers and Share Buybacks Regulatory Framework
Hong Kong Takeovers, Mergers and Share Buy-backs
2:03.8
Ownership and Ethics of Training Data in Generative AI
AI, Copyright, and the Ownership of Training Data
1:55.4
Transitioning from Generative AI Chatbots to Autonomous AI Agents
From Chatbots to Agents: The Phase of AI
2:02.3
Regulatory Compliance Frameworks for Virtual Assets and Tokenized Securities
Virtual Assets and Tokenised Securities: Regulatory Issues for Financial Intermediaries
2:05.3